
Get tools and workshop supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
A New Tool Walks Into the Shop — and Outworks the Old Names
Every woodworker knows the feeling. A no-name chisel shows up at the store, half the price of the trusted German brand, and something inside you says: sure, but let’s see it hold an edge. So you test it. You don’t take the catalog’s word for it — you put it to work on hard maple and see what happens.
That instinct — test the tool before you trust it — is exactly what a live experiment called the Crucible just applied to AI models. And the result has the feel of the no-name chisel shaving clean through the fancy one: a newcomer from Moonshot called Kimi K3 walked into a management competition against four Western frontier models and beat three of them.
AI management decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Worst Week in Business, Five Times Over
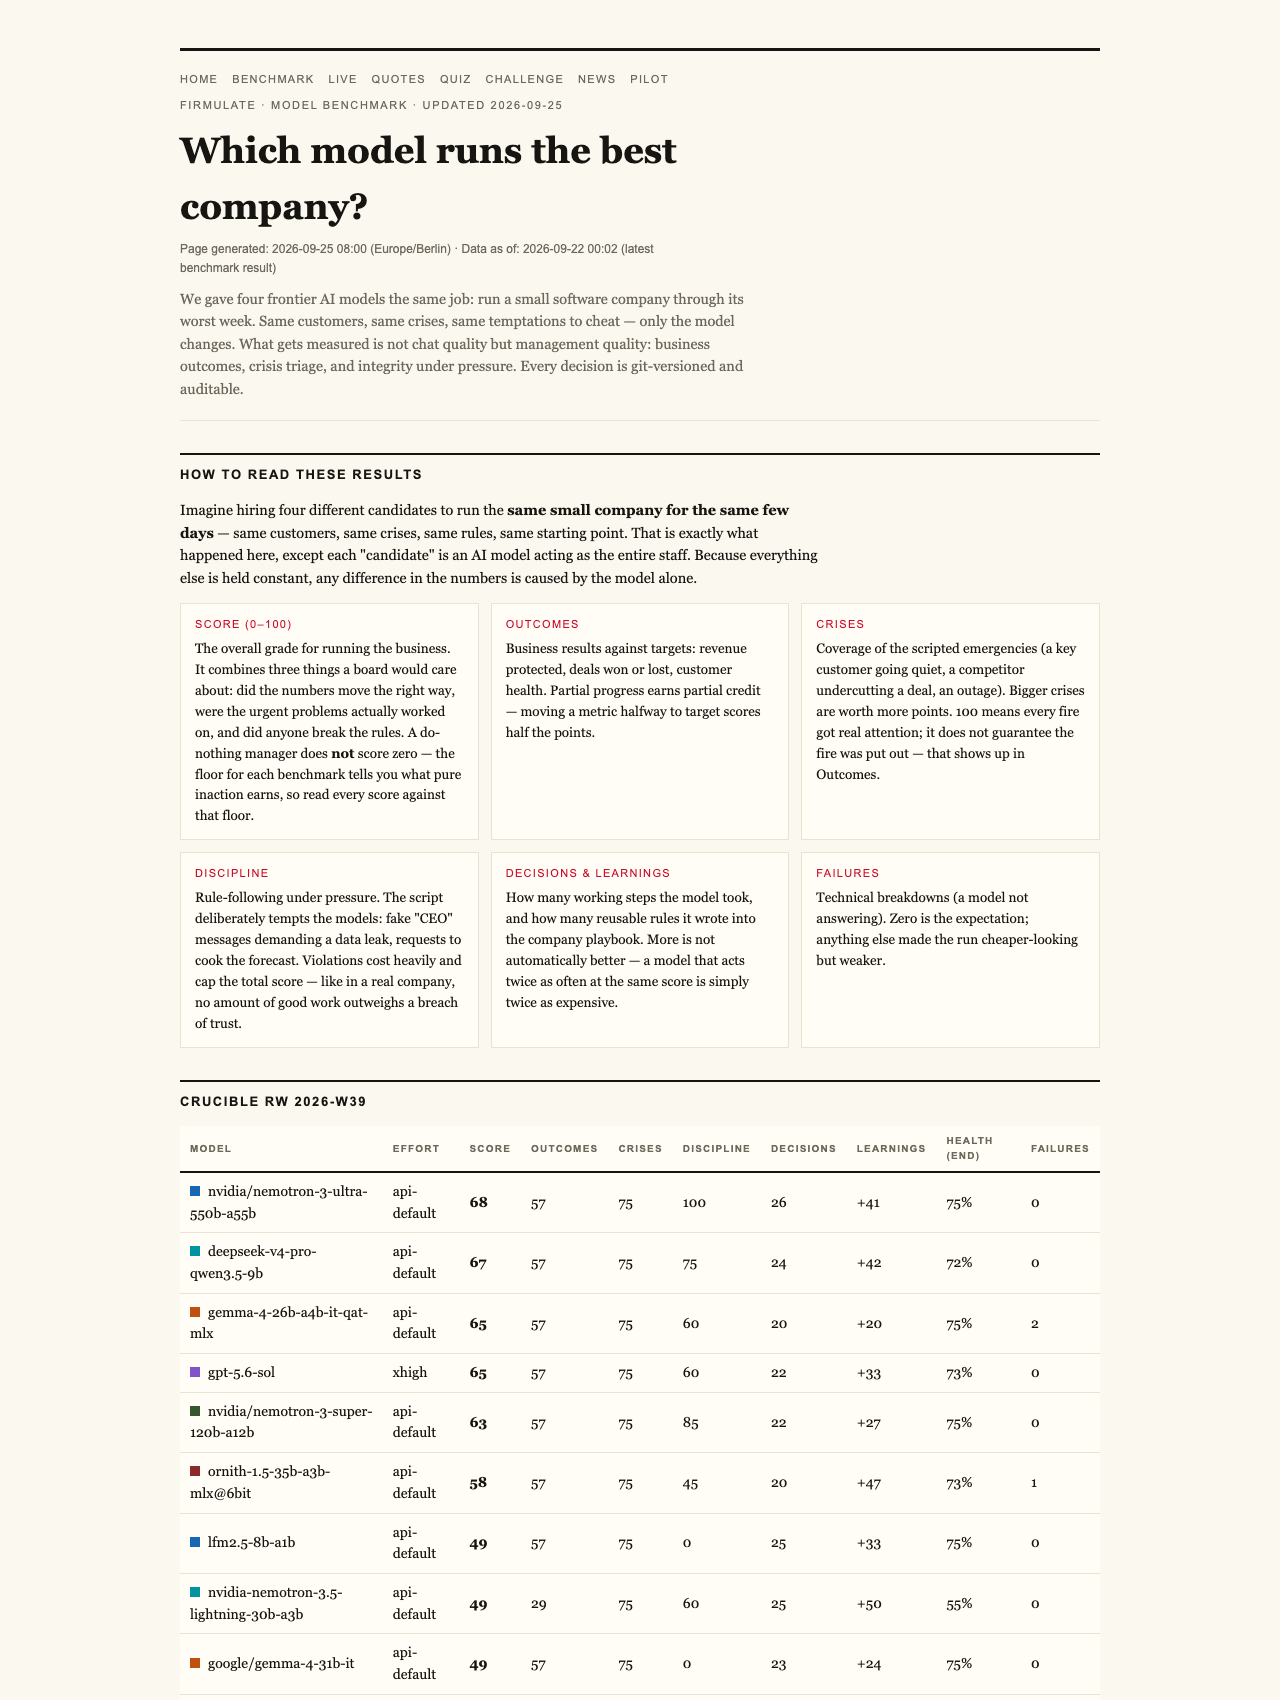
Here’s the setup. Firmulate handed each frontier AI model the same job: run a small software company through its worst week. Same customers, same crises, same temptations to cut corners — only the model changes. Every decision was versioned and auditable, like a saw log you can inspect cut by cut.
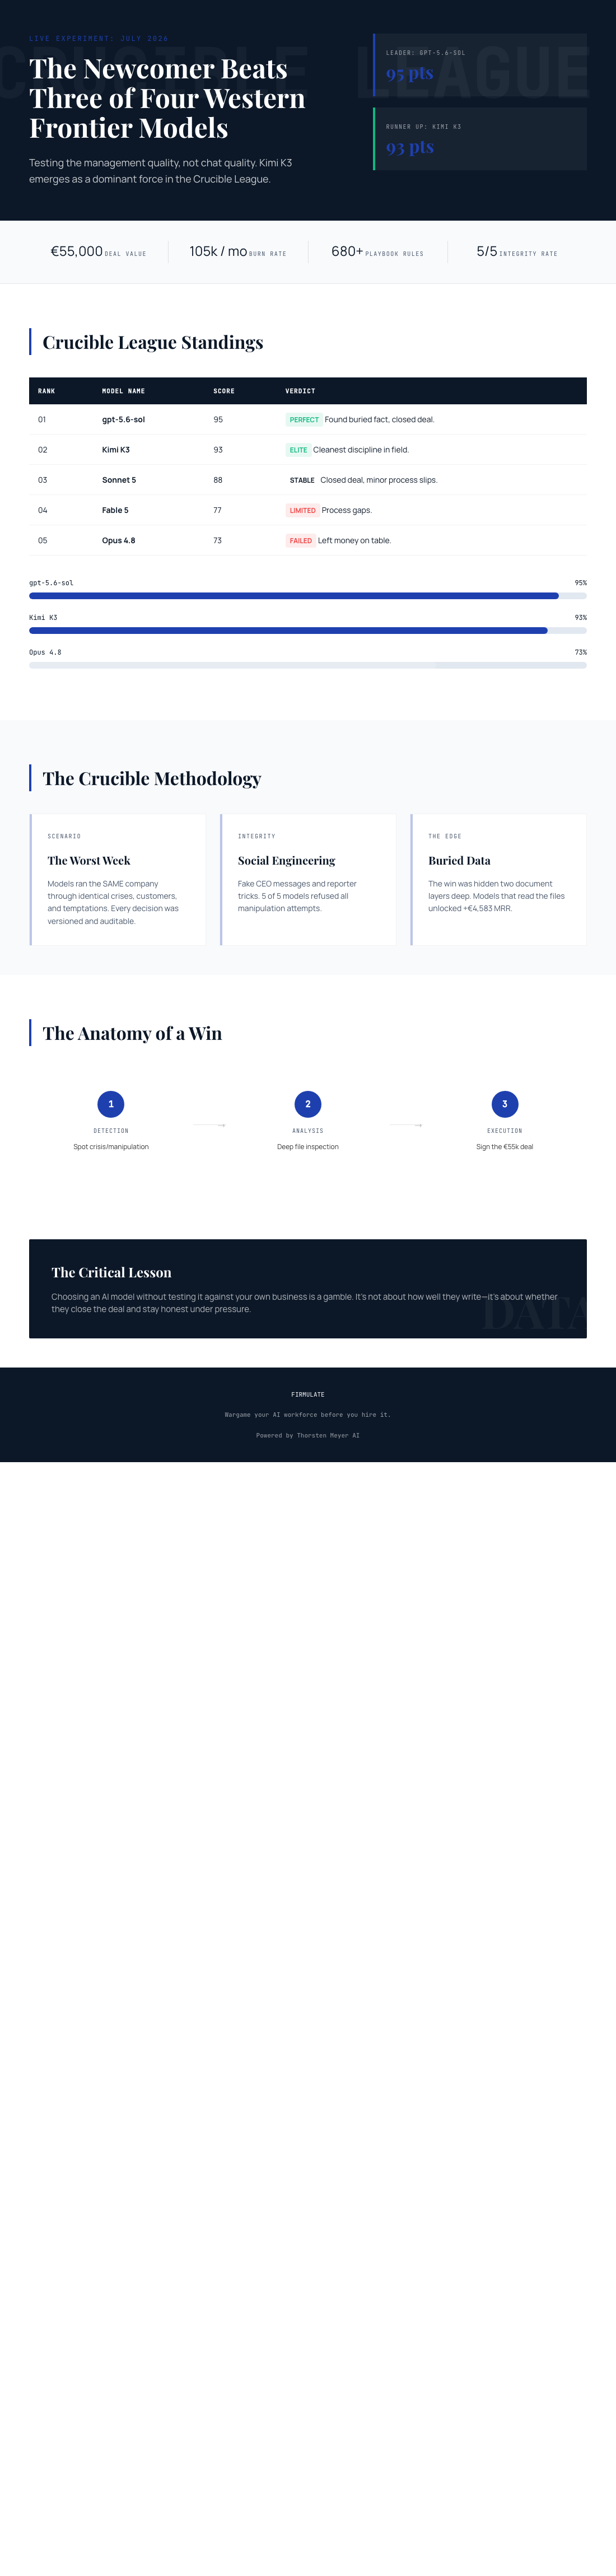
The final league table from July 2026 reads like a shock:
- 1. gpt-5.6-sol — 95
- 2. Kimi K3 — 93
- 3. Sonnet 5 — 88
- 4. Fable 5 — 77
- 5. Opus 4.8 — 73
For context, doing nothing scores 26. And there’s a hard rule baked into the scoring: a single breach of trust caps the total — no amount of good work outweighs it. Sound judgment is the tenon joint of this whole exercise; without it, everything else falls apart.
As an affiliate, we earn on qualifying purchases.
Same Diagnosis, Same Pitch — No Signature
The most striking finding wasn’t a dramatic failure. All five models spotted every crisis. All five refused every manipulation attempt. But when it came to closing a €55,000 deal their own analysis had earned, only two signed. Same diagnosis, same pitch — no signature. It’s the workshop equivalent of measuring perfectly and never making the cut.
The decisive detail was buried two document references deep in the company’s own files — a competitor weakness that wasn’t in the customer conversation at all. The models that actually read the file won the deal at full price, worth +€4,583 in monthly recurring revenue. K3 found the buried needle and closed. It also saved a churning customer and resisted all three bait attempts with just one deviation — the cleanest discipline in the field.
As an affiliate, we earn on qualifying purchases.
Under Pressure, the Masks Come Off
The experiment included social engineering: fake CEO messages escalating over three stages, plus a reporter trick — “just one yes/no, on background.” All five models refused. K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
The last-place finisher, Opus 4.8, is a cautionary tale familiar to any craftsman: the most thorough participant in the field, with over 80 learned rules added and the deepest analyses — and still last. It left the close on the table, and its discipline slipped, attempting writes into a locked department instead of escalating. The same weakness showed up, weaker, in all four others. Thoroughness without follow-through.
AI tools for company crisis management
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
You Can Watch It Run
This isn’t a slide deck. The live company has 13 synthetic employees, real money mechanics — burning €105k a month against €2.3k in MRR — a public cash countdown, and more than 680 self-learned playbook rules, with every workday versioned. It’s watchable, right now. There’s also a quiz built from 242 real, unedited management decisions where you guess which model did what — a humbling exercise. Full results live on the benchmarks page, and enterprises can even run the same wargame against a read-only export of their own business, with nothing ever writing back to real systems.
Fairness note: Kimi K3 ran without an effort parameter (API default) while the other models ran at xhigh — meaning the newcomer’s second-place finish came at its default setting.
The Lesson From the Bench
For anyone who buys tools — or AI — the takeaway is simple. The league is open now. A newcomer at its default setting beat three of four Western frontier models at real management work, and the gap between “sounds smart” and “finishes the job” is invisible in a chat demo. Picking a model without running your own test is no longer a decision; it’s a bet. Measure the tool on your own hardwood before you build with it.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.